
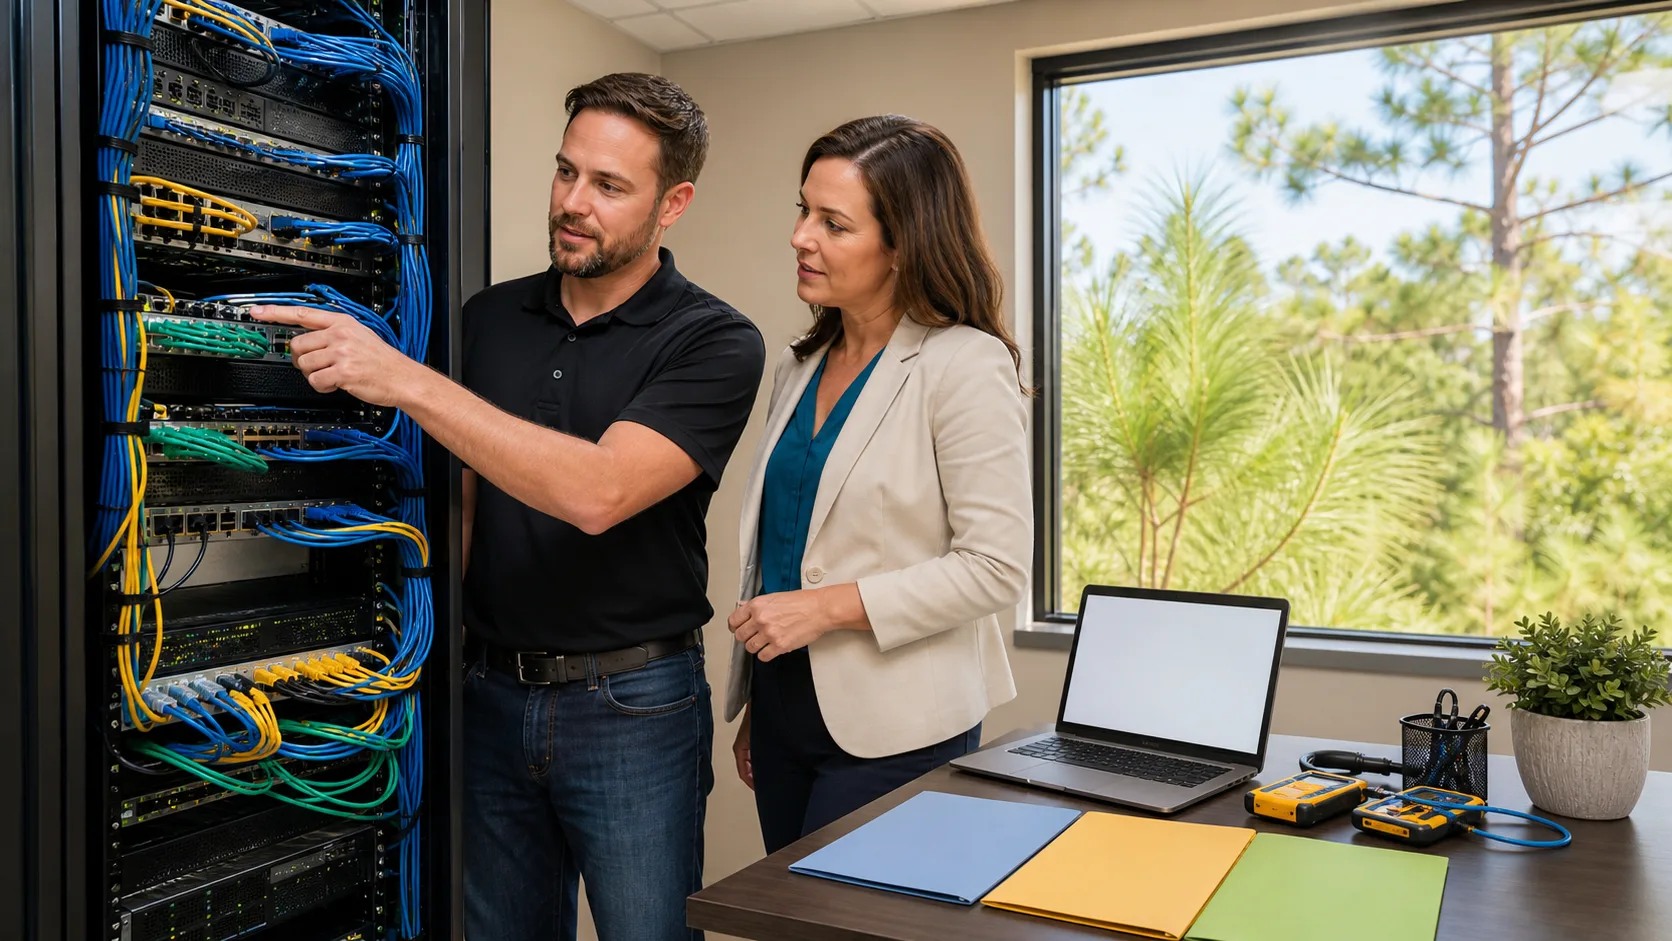
Stop Losing Days to Downtime in the Wiregrass
Downtime in a small business is not just when “everything is down.” It is the power flicker that reboots your PC, the choppy Wi-Fi that kicks staff out of a cloud app, or the frozen line-of-business system five minutes before a deadline. One bad morning like that in Dothan or anywhere in the Wiregrass can throw off an entire week.
Even an hour of disruption stacks up fast. Orders slip. Calls get missed. Staff stay late to catch up and start the next day tired and frustrated. People learn to work around IT instead of trusting it, and that slow drain hits revenue, morale, and even compliance.
Most of this is not random bad luck. When you look at root causes like power, ISP, hardware, and cloud apps through a clear IT management lens, patterns show up. That means you can predict and prevent many problems before they hit your team. For businesses across the Wiregrass, heading into heavier storm fronts and year-end workloads, having a local partner that understands how systems behave here is a big deal.
Why Downtime Happens More Than You Think
Downtime is not only a total outage where the lights are off and everyone stands around. It also includes:
- Full outages, like a dead internet circuit or a down server
- Micro-outages, short drops that kick people out of calls or cloud apps
- Slowdowns, when systems are “up” but so sluggish that real work stops
In the Wiregrass, certain triggers show up again and again. Thunderstorms and fall storm fronts bring small power hits and spikes. Older strip malls often have overloaded circuits. Shared office buildings may rely on cheap ISP plans not built for business use. Many offices still run on DIY Wi-Fi with gear meant for a living room, not a staff of ten or twenty.
The key point is that downtime usually comes from a chain reaction. A small power blip hits the modem, the modem locks up, the router never fully recovers, and suddenly your cloud CRM feels “flaky.” It is not magic; it is cause and effect. When you manage IT with a root-cause mindset, you break that chain early.
Proactive IT management in the Wiregrass turns unknowns into a clear list of monitored items, known weak spots, and defined responses. You move from reacting in panic to working a simple plan.
The Root-Cause Map: Power, ISP, Hardware, Cloud Apps
Power reliability
Short power hits, brownouts, and surges often do more damage than a full outage. They can:
- Corrupt open files
- Shorten the life of PCs, servers, and network gear
- Cause random reboots that feel “mysterious”
Core protections include correctly sized UPS units on servers, switches, and key PCs, quality surge protection, and power conditioning where voltage is unstable. Clear shutdown steps for different power events also matter. With fall storms and heavier electrical loads, this is a smart time to review how your office handles shaky power before busy season peaks.
ISP and local network stability
Internet and local network issues are another main root cause. The usual failure points are:
- Low-grade modems from bargain plans
- No backup connection if the primary ISP fails
- Poor Wi-Fi design with dead spots or overloaded access points
- Unmanaged switches that lock up under heavy use
A layered design helps keep people working. That often means a primary ISP, a secondary backup such as wireless or another carrier, and traffic rules that keep business tools online first when bandwidth is tight. Ongoing monitoring for uptime, packet loss, and latency lets you spot trouble before your staff starts shouting about “the internet.”
Hardware lifecycle and aging infrastructure
Old or mismatched gear is a silent source of chaos. Aging workstations, overworked servers, and cheap firewalls can cause strange lockups, slow logins, and frozen apps.
Good IT management in the Wiregrass includes:
- A full asset inventory
- A standard replacement age for each device type
- A small set of approved models for PCs, laptops, and network gear
Spreading refreshes across the year keeps hardware current without last-minute, stressful buying sprees.
Cloud apps and vendor dependencies
Line-of-business systems, CRMs, and accounting tools now live in the cloud. When those vendors struggle, your team feels it instantly.
Practical strategies include:
- Knowing which regions or data centers your key apps use
- Watching status dashboards or alerts for major vendors
- Planning offline workflows for short outages
- Having simple fallback tools or manual processes for core tasks
Good IT management in the Wiregrass maps which vendors are truly mission-critical and defines what your team will do if any one of them is down.
Building a Wiregrass Downtime Playbook
Map your business-critical processes
Start with the work, not the tech. List the key processes that keep your doors open, such as:
- Phones and customer communication
- Scheduling and dispatch
- Point-of-sale or payment processing
- EHR or client records
- Inventory and shipping
For each one, ask what “unacceptable downtime” means. Then tie each process to its dependencies: specific power circuits, ISP links, Wi-Fi zones, servers, and cloud apps. That map gives you a clear target for downtime prevention.
Prioritize by impact, not just likelihood
Not every risk is equal. A rare power event that can stop all revenue may deserve more attention than a glitchy reporting tool. A simple impact-versus-likelihood view helps sort your list.
Estimate your hourly cost of downtime by thinking about lost production, staff idle time, overtime, and any reputational damage. That rough number guides where you invest in monitoring, backups, and redundancy first.
Turn chaos into checklists and standards
Once you know what matters most, you can standardize. That includes:
- Where and how backups run
- How devices are configured and patched
- What “healthy” looks like for each system
Short, clear runbooks are key. For example, “What to do first when the internet dies” or “Steps when the main cloud app is slow.” IT management in the Wiregrass works best as an ongoing habit, not a one-time cleanup, especially as your staff, locations, and apps grow.
Your 30-, 60-, 90-Day Downtime Reduction Plan
First 30 days: Assess and stabilize
Start by seeing the whole picture. In the first month, you would:
- Inventory power gear, ISP contracts, modems, routers, switches, servers, PCs, and core cloud apps
- Replace weak UPS batteries and add surge strips where missing
- Secure Wi-Fi and move to a business-grade router
- Patch urgent security risks on servers and endpoints
- Set up basic monitoring for internet uptime and key systems
- Begin an incident log to record every outage and slowdown
Days 31 to 60: Fix the biggest risks
With some data in hand, go after the top offenders. During this phase:
- Address unstable ISP circuits or faulty network gear
- Add ISP redundancy or cellular failover for locations with frequent internet issues
- Consider moving fragile on-premises apps into more reliable hosted or cloud options
- Start a structured hardware refresh, focusing on the oldest or most problematic devices
- Standardize on a few PC and laptop models to simplify support and spares
Days 61 to 90: Optimize, document, and train
By now, the major fires should be under control. The last phase is about building muscle:
- Write a clear downtime playbook for power events, ISP outages, hardware failures, and cloud app issues
- Train staff on how to report problems with helpful detail and follow basic triage steps
- Review what changed in the first 90 days and update priorities
- Set a quarterly review rhythm with your IT partner to stay aligned with seasonal patterns and business growth
Turn Wiregrass Downtime Risks Into a Competitive Edge
Staying online when others are scrambling is a real local advantage. In Dothan and across the Wiregrass, the businesses that keep phones, cloud apps, and point-of-sale running through storms and ISP hiccups are the ones customers remember.
Ask yourself a few simple questions. When was the last time you tested a backup? How long can your team work without internet or a key cloud app? Which single failure would hurt you the most?
A structured root-cause framework, paired with a focused 30-, 60-, 90-day plan, turns downtime from a constant headache into something you actively control. With a partner like 404IT that lives and works in the Wiregrass, IT management becomes less about firefighting and more about keeping your people productive, no matter what the day brings.
Strengthen Your Wiregrass Business With Reliable IT Support
If you are ready to reduce downtime and gain clarity around your technology, our team at 404IT is here to help. Explore how our IT management in the Wiregrass can secure your systems, streamline your operations, and free your staff to focus on what matters most. To discuss your specific needs or schedule a consultation, contact us today.
Comments are closed